ProCat Solutions
What local AI can do today, from an RTX rig to a jailbroken PS5
A jailbroken PS5 writes twenty tokens a second, a book-sized mini PC runs a 235-billion-parameter model. What your own AI machine costs, what it draws, and when the cloud wins.
A jailbroken PlayStation 5 can write roughly twenty tokens a second, about fifteen words, with a 27-billion-parameter language model. On the console’s CPU, the same model manages one token a minute. The gap between those two numbers explains why memory is the part that matters most if you want to run AI on your own hardware.
The PS5 experiment is a hobby project and does not work without a jailbreak. The shift it points to is real, though. Open models such as Qwen, DeepSeek and OpenAI’s gpt-oss family are now good enough for a company to have them write code, summarise contracts or search internal documents without a single line leaving the server room. The open question is what the hardware costs, and how much power it draws.
Memory decides
A language model reads through its own weights for every word it produces. If they do not fit in the graphics card’s memory, the machine falls back on slow system RAM and speed collapses. Pace is set mainly by how much memory there is and how fast it can be read.
Two tricks help. Quantisation squeezes weights from 16 bits to 4, so a 32-billion-parameter model fits in roughly 20 gigabytes without a noticeable drop in quality. In mixture-of-experts (MoE) models only part of the network works on each word, 3 billion out of 30 billion in a typical case, which makes them far quicker than their size suggests. Speed is measured in tokens per second; at 15–20, text appears at about reading pace.
The obvious route: a big graphics card
The simplest answer is a high-end gaming card. According to hardware-corner.net, an RTX 5090 runs Qwen3 32B at 4-bit at 44–61 tokens a second, and the MoE Qwen3-Coder-30B-A3B at more than 240. Nobody reads that fast.
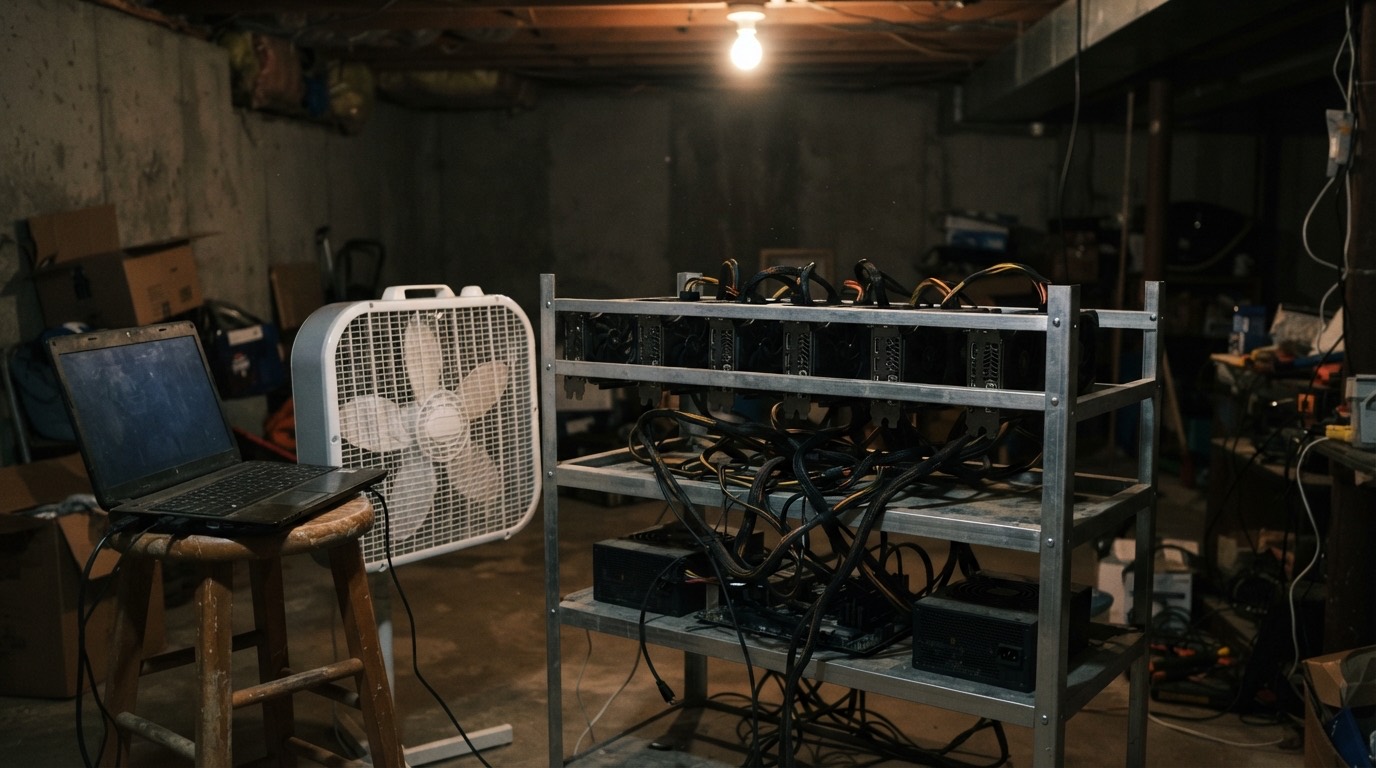
The budget option is a used RTX 3090. The 2020 card has 24GB of memory and manages about 37 tokens a second with a 32-billion-parameter model; two of them run a 70-billion model at 15–20. The electricity company collects the difference: a single 3090 draws 350 watts, the whole machine sits around 850 under load, and in summer you can feel it in the room.
Book-sized machines, under 200 watts
The surprise of the past year has been the mini PC. Boxes built around AMD’s Ryzen AI Max+ 395, known as Strix Halo, carry 128GB of shared memory that the built-in graphics can draw on. Measurements put Qwen3-30B-A3B at about 100 tokens a second and the huge Qwen3-235B at 11, while the machine pulls 120–140 watts from the wall. The 128GB GMKtec EVO-X2 now sells for around $2,000–2,300 after memory prices rose.
In the same weight class sit Nvidia’s desktop DGX Spark (128GB, $4,699), which runs gpt-oss-120b at 38–55 tokens a second, and Apple’s Mac Studio. The version with an M3 Ultra and 512GB of memory loads the full 671-billion-parameter DeepSeek R1 at 4-bit and runs it at 17–18 tokens a second, on less than 200 watts according to TechRadar.
The strange end of the scale
The PS5 is not the only machine pressed into a job it was never designed for.
- PlayStation 5. The PS5LM project ported the popular llama.cpp to the jailbroken console. Its 16GB of GDDR6 with 448GB/s of bandwidth beats many office graphics cards on paper. Smaller models run at more than 100 tokens a second.
- A Mac Studio cluster. Software called exo treats several Macs as one large machine. Since macOS 26.2 added RDMA over Thunderbolt 5, four Mac Studios together run Qwen3 235B at 32 tokens a second. Jeff Geerling assembled 1.5 terabytes of shared memory this way, for roughly $40,000.
- Raspberry Pi 5. On the credit-card-sized board, a one-billion-parameter Llama 3.2 runs at 11–20 tokens a second and a three-billion Qwen at about 5. Enough for a smart home and simple tasks.
- Windows 98. EXO Labs ran a language model on a 1997 Pentium II with 128MB of RAM, bought on eBay. A tiny 260,000-parameter model ran at 39 tokens a second; Llama 3.2 1B at 0.0093, or 107 seconds for a single token.
In numbers
| Machine | Memory | Measured example | Power | Price (approx.) |
|---|---|---|---|---|
| RTX 5090 desktop | 32 GB | Qwen3 32B: 44-61 tok/s | high (hundreds of W) | card alone ~$2,000+ |
| 2× RTX 3090 (used) | 2×24 GB | 70B model: 15-20 tok/s | ~350 W per card | used market |
| Ryzen AI Max+ 395 mini PC | 128 GB shared | Qwen3-235B: ~11 tok/s | 120-140 W | $2,000-2,300 |
| NVIDIA DGX Spark | 128 GB shared | gpt-oss-120b: 38-55 tok/s | low | $4,699 |
| Mac Studio M3 Ultra | 512 GB shared | DeepSeek R1 671B: 17-18 tok/s | <200 W | premium |
| Jailbroken PS5 | 16 GB GDDR6 | Qwen 27B: ~20 tok/s | console | console + jailbreak |
| Raspberry Pi 5 | 8-16 GB | Llama 3.2 1B: 11-20 tok/s | a few W | cheap |
The figures come from different tests with different settings. They show orders of magnitude, not a league table.
What people use it for
- Programming. Qwen3-Coder and its peers suggest code locally, explain old code and write tests for it. The source code never leaves the company, which many client contracts require anyway.
- Text. Drafts, summaries, translations, emails. For contracts and internal material, the main argument is that nothing goes to a third party.
- Audio and images. Transcribing recordings, subtitling video and generating images, on the same hardware.
- Company knowledge base. An assistant that answers from the company’s own documents. We wrote about it in more detail in connection with Abisearch.
Your own machine or the cloud?
| Aspect | Local machine | Cloud (API or rented GPU) |
|---|---|---|
| Getting started | one-off hardware cost | none, starts immediately |
| Running cost | electricity, maintenance | pay per use, expensive at high volume |
| Data protection | data never leaves the machine | depends on provider and contract |
| Best models | open models only | the strongest closed models too |
| Scaling | as much as the machine has | practically unlimited |
| Offline use | yes | no |
| Operations | our job | the provider’s |
If you would rather not buy hardware, you can rent: an H100 server GPU costs roughly $2–4 an hour in 2026, and Lambda and RunPod price within that band. For steady daily use, your own machine pays for itself quickly; for occasional peaks, renting or a cloud API is cheaper.
Where to start
For a company, buying a machine is rarely step one. First work out what it is for, how large a model is enough, and how many people will use it at once. That decides whether a mini PC in the corner of the office will do, an RTX server is needed, or the open model is better off in the cloud. We build systems like these, including models installed on your own server and the internal interface that goes with them.
Sources
- PS5LM on GitHub, Tom’s Hardware on the native fork
- Mac Studio M3 Ultra and DeepSeek R1 (MacRumors), power draw (TechRadar)
- RTX 5090 LLM benchmarks (hardware-corner.net)
- RTX 3090 for local LLMs (llmhardware.io)
- Strix Halo benchmarks (GitHub), power draw (TechPowerUp), GMKtec EVO-X2 (Tom’s Hardware)
- DGX Spark benchmarks (Spheron)
- Mac Studio cluster with RDMA (Jeff Geerling), AppleInsider
- Llama on Windows 98 (Hackaday)
- Raspberry Pi 5 benchmarks
- H100 rental prices (Spheron, Lambda), RunPod